While Apache Druid offers unparalleled real-time analytics, its operational complexity often creates a significant bottleneck for data teams. This article introduces the iunera Druid MCP Server, a revolutionary open-source tool that builds a conversational bridge to Druid's powerful engine. Learn how it leverages a Large Language Model (LLM) and the Model Context Protocol (MCP) to translate simple, natural language commands into complex data workflows, removing operational overhead and making advanced analytics accessible to everyone.
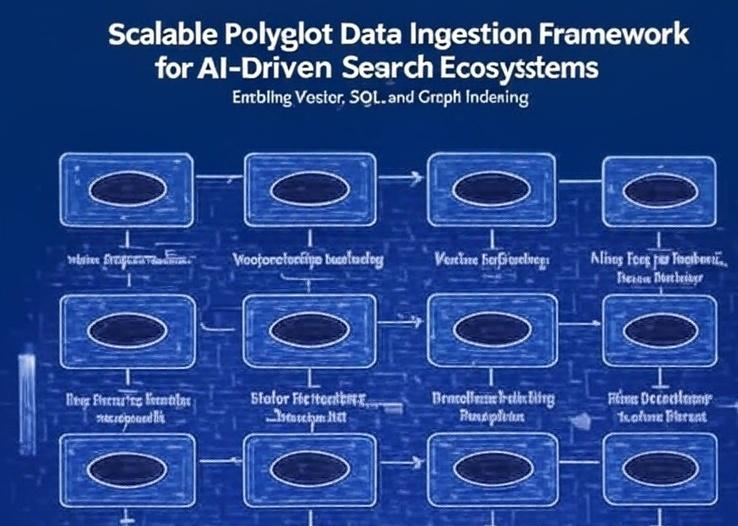
Explore a scalable polyglot data ingestion framework for AI-driven search ecosystems, supporting vector, SQL, and graph indexing. A flowchart details 6 steps for preprocessing and embedding, enabling robust RAG search.
An in-depth analysis of the intricate challenges of vector-only Retrieval-Augmented Generation (RAG) pipelines, spotlighting these issues […]
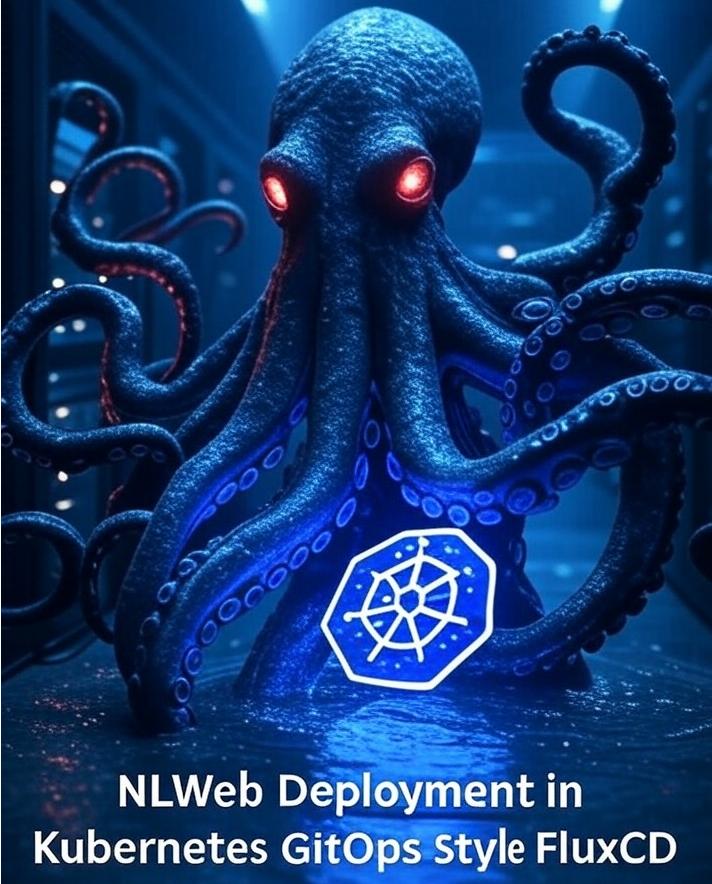
NLWeb is revolutionizing web development by integrating advanced machine learning and AI, as showcased in recent insights. Picture NLWeb as a powerful kraken, its tentacles infused with the Kubernetes (K8s) logo, symbolizing the robust infrastructure behind these AI-driven solutions. NLWeb delivers dynamic, intelligent websites that adapt and evolve, offering unparalleled user experiences.
Everybody's talking about it but everyone seems to have a different perception of it. We breakdown the meaning of eCommerce personalization and how it's important for the ever growing e-business world.
Big Data and AI might be the next big things in tech. What are the next big things in Big Data and AI?
There's an increasing need for student-centric education. We look at how Big Data meets this need.
Does hyper-personalisation mean personalisation getting hyper from caffeine? We take a very brief look at what it is and why it's necessary.
We spoke to Jon Bratseth, data architect of Verizon Media and Vespa.ai, about Big Data maturity and serving.
We spoke to a Machine Learning expert to learn more about the Agile approach in data science.